# Reading Code a Model Wrote {#sec-ai-r}
```{r}
#| label: ch20-setup
#| include: false
suppressPackageStartupMessages(library(tidyverse))
mv_data <- Sys.getenv("MV_DATA", "https://viz.marginoferrormedia.com/data")
mv_theme <- Sys.getenv("MV_THEME", "https://viz.marginoferrormedia.com/figures/mv-theme.R")
source(mv_theme)
mv_set_chapter(7)
st <- read_csv(file.path(mv_data, "ch07-incarceration-state.csv"), show_col_types = FALSE)
```
## The Chart That Ran Without Error
An analyst at a regional agency was asked for one chart. Which states had seen the largest growth in their prison populations since 1990? She described the dataset to a language model, pasted the column names, and asked for a ggplot. The code came back in a few seconds, ran without an error, and drew a bar chart. Four states at the top of the chart had bars that ran off the edge, and several states she expected to see were missing. She trimmed the chart to the states that looked reasonable. It went into a briefing.
The four states ran off the edge because none of their counties reported in 1990, so growth from zero was infinite. The missing states had no counties reporting in 2015. The states that looked reasonable were also wrong. The dataset builds state prison counts from county records, and the number of counties reporting changes from year to year. A state that went from 36 reporting counties to 40 shows growth that comes partly from more prisoners and partly from more counties reporting. The model had done what it was asked, which was to compute growth from the first year to the last. Nobody had asked it whether the first year and the last year counted the same counties.
The code did what was asked and the chart was still wrong. This chapter is about reading code closely enough to see that before the chart is used.
## What the Model Is Good At
A language model turns a description of what you want into code that runs. It does this well and quickly. Three uses save time in most sessions.
**Translation.** You know what you want and cannot remember the function. "Group by state, take the mean of the rate, sort descending" becomes a `dplyr` pipeline. The model knows the vocabulary of `dplyr`, `tidyr`, and `ggplot2` better than most people who use them daily.
**Explanation.** Paste code you inherited and ask what each line does. For ordinary tidyverse code the explanation is reliable, and it is faster than reading documentation for six functions.
**Debugging.** Paste the error, the code, and the first few rows of the data. The model finds the missing comma, the wrong argument name, and the column that is a character when it should be a number. This is the task where the model saves the most time.
Each of these works because the model matches your request to patterns it has seen many times. The same matching is where it fails when your data differ from the pattern.
## What It Does Not Know
The model does not know your data. It knows what data like yours usually looks like, and it writes code for that. When your data differ, the code still runs. Four kinds of failure appear often.
**The silent assumption.** The analyst's dataset had a `prison_reported` column that recorded how many counties reported in each state and year. The model did not use it, because a request for growth does not usually involve a coverage check. The code assumed the counts were comparable across years. The output gave no sign of that assumption.
**The plausible default.** Asked for a chart of growth, a model draws counts. Counts of prison populations are dominated by state size, so the chart ranks states by population rather than by change. Chapter 7 of *Make It Visible* spends a section on this. The model has seen text like that chapter and still draws counts, because counts are what most code it has seen draws.
**The invented function.** The model sometimes names an argument that does not exist, or a package that does not exist, or uses a function that was retired two versions ago. `gather()` and `spread()` still appear in model-written code, years after `pivot_longer()` and `pivot_wider()` replaced them. The code may run today and stop running after the next package update.
**The confident method.** Asked for a test, the model picks one and writes it. It will fit a linear model to a count, run a paired test on independent groups, or report a correlation on an ordinal scale, and the output will be formatted as cleanly as if the choice had been right.
None of these produces an error message. A reader who knows the data can find each one.
## Read, Run, Check
The habit this book has been building has three steps, and they apply to model-written code exactly as they apply to your own.
### Read It Before You Run It
Read the code the way you would read a paragraph someone else wrote, one sentence at a time, asking what each one claims. Here is the code the analyst received, lightly cleaned.
```{r}
#| label: ch20-model-draft
#| eval: false
st |>
  filter(year %in% c(1990, 2015)) |>
  group_by(state) |>
  summarise(growth = (prison[year == 2015] - prison[year == 1990]) / prison[year == 1990]) |>
  arrange(desc(growth)) |>
  slice_head(n = 10) |>
  ggplot(aes(growth, reorder(state, growth))) +
  geom_col() +
  labs(title = "Prison population growth by state, 1990 to 2015")
```
The code makes four claims, and each needs a question. What does `prison` count, and is it the same thing in both years? Is a change in a count the right measure, or should it be a rate? What happens to a state whose 1990 value is zero? Why these two years and not the whole series? Reading the code this way requires no running. It requires knowing the data, and the model does not know the data.
### Run It on Something You Can Check
Run the code on a slice you know the answer for. Start with the two endpoints and ask how much of the country each one covers.
```{r}
#| label: ch20-check-coverage
st |>
  filter(year %in% c(1990, 2013, 2015)) |>
  group_by(year) |>
  summarise(counties_reporting = sum(prison_reported),
            prison_total = sum(prison)) |>
  mutate(across(everything(), round))
```
The number of reporting counties rises from 1990 to 2013 and then falls by a quarter by 2015. The prison total falls with it. A chart that compares 2015 to 1990 compares two partial counts with different gaps. Now look at the states.
```{r}
#| label: ch20-check-states
st |>
  filter(year %in% c(1990, 2015)) |>
  select(state, year, prison_reported, counties) |>
  pivot_wider(names_from = year, values_from = prison_reported, names_prefix = "reported_") |>
  filter(reported_1990 == 0 | reported_2015 == 0 | reported_1990 != reported_2015) |>
  arrange(reported_1990) |>
  slice_head(n = 12)
```
Four states had no counties reporting in 1990, which is where the infinite bars came from. Eight had none in 2015, which is where the missing states went. And many of the rest changed their coverage between the two years. Two summaries were enough to find the error.
### Check the Output Against the Claim
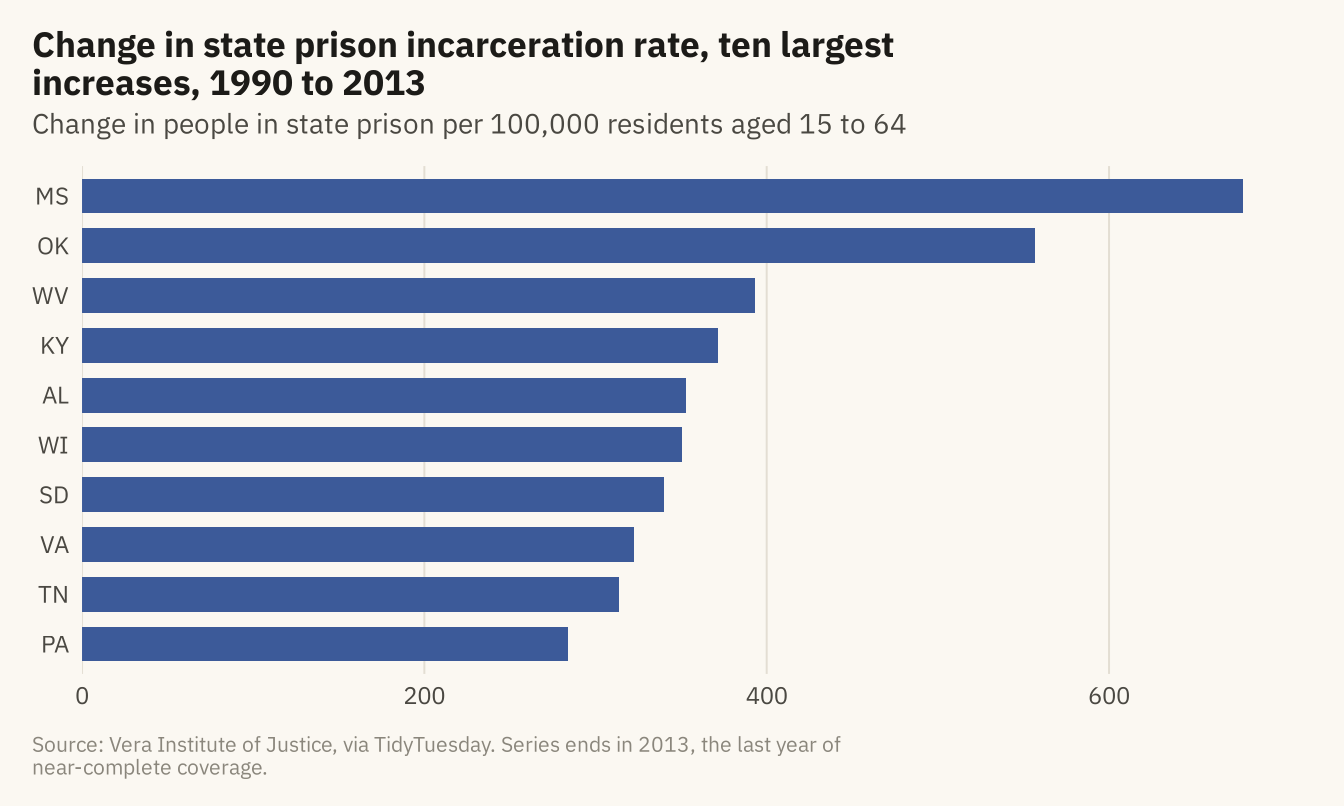
Rewrite the code so that it says what the chart will claim. Use the rate rather than the count. End the series in 2013, the last year of near-complete coverage. Keep only states with reporting counties in both years, and say so in the caption.
```{r}
#| label: fig-ch20-rate
#| fig-height: 4.2
#| fig-cap: "Change in the state prison incarceration rate, 1990 to 2013, ten largest increases. Only states with reporting counties in both years are included, and the series ends in 2013, the last year with near-complete county coverage. Source: Vera Institute of Justice, via TidyTuesday."
top <- st |>
  filter(year %in% c(1990, 2013), prison_reported > 0) |>
  group_by(state) |>
  filter(n() == 2) |>
  summarise(change = prison_rate[year == 2013] - prison_rate[year == 1990]) |>
  slice_max(change, n = 10)

ggplot(top, aes(change, fct_reorder(state, change))) +
  geom_col(fill = mv_accent(), width = 0.7) +
  scale_x_continuous(expand = expansion(mult = c(0, 0.05))) +
  labs(title = "Change in state prison incarceration rate, ten largest increases, 1990 to 2013",
       subtitle = "Change in people in state prison per 100,000 residents aged 15 to 64",
       x = NULL, y = NULL,
       caption = mv_source("Vera Institute of Justice, via TidyTuesday", "Series ends in 2013, the last year of near-complete coverage")) +
  theme_mv(grid = "x")
```
The chart now answers the question that was asked. The rate compares states of different sizes, and the 1990 to 2013 window keeps the counts comparable. The model would have produced this version on request, if the request had included what the check found. The check is the part the model does not do on its own.
::: {.callout-warning}
## AI Reality Check
Ask a model to "add a check that the data are comparable across years" and it will often write a check that passes. A check written by the same process that wrote the code tends to test the assumptions the code already made. Write the check yourself, from what you know about where the data came from. If you do not know where the data came from, find that out first. Code cannot supply that information.
:::
## Asking Better
Four habits improve the code a model returns.
**Name the tools.** "Using `dplyr` and `ggplot2`" produces a pipeline in one style. Leaving it out produces a mixture of base R and tidyverse that is harder to read.
**Show the data.** Paste the column names, the types, and five rows. Say what each column measures and where it came from. A model that knows `prison_reported` records coverage will sometimes use it unprompted.
**Ask for the steps.** "Write the code and say what each step does" slows the model down and gives you a sentence to check against each line.
**Ask for the doubts.** "What would make this analysis wrong?" is a question the model answers well, because it has read many postmortems. It will list the coverage problem among the possibilities. It will not know which possibility applies to your data, and you will need to check that yourself.
## Keeping the Record
Model-written code belongs in your script once you have read, run, and checked it, and not before. Three practices help when someone later asks how the analysis was done.
**Keep the prompt.** The prompt is part of the method. Save it in a comment at the top of the chunk or in the project notes, so that a reader can see what was asked.
**Keep the checks.** The coverage summary above is the evidence that the chart is right. Keep it in the document.
**Say what the model did.** A line in the methods, or a note on the chart, that says the first draft of the code was model-written and was checked against the data by the analyst. There is no settled norm yet on disclosing model-written code. A sentence that says so costs nothing.
::: {.callout-important}
## Ethics Moment
The analyst in the opening story put her name on the briefing. The model did not. When the chart turned out to be wrong, the responsibility was hers, and it would have been hers if the code had been perfect. A model cannot be held responsible. What follows for how much checking is enough before a result leaves your desk?
:::
## Putting It All Together
A model writes code that runs. Whether the code does the right thing for your data is a question the model cannot answer, because it has never seen your data. Read the code as a set of claims. Run it on a slice you can verify by hand. Check the output against the sentence the chart will support. Keep the prompt, keep the checks, and say what the model did. These are the habits this book has taught throughout, and they matter more when a tool writes the syntax.
## Further Reading
- Wickham, H., Çetinkaya-Rundel, M., and Grolemund, G. (2023). *R for Data Science*, 2nd edition. The chapters on data import and tidying are the reference for the checks in this chapter.
- Patil, V. (2027). *Make It Visible*, Chapter 7 (Change Over Time) and Chapter 12 (From Data to Story). The coverage trap in the jail data, and a method for marking the claims a model-written caption does not support.
- Broman, K. W. and Woo, K. H. (2018). Data organization in spreadsheets. *The American Statistician*, 72(1), 2-10. Most model-written code assumes data organized the way this paper recommends.
## Key Terms {.unnumbered}
- **Coverage.** The share of the units that should be in a dataset that are in fact recorded for a given year or place.
- **Silent assumption.** A condition the code requires and does not test, such as comparable counts across years.
- **Verification.** Reading code as a set of claims, running it on a case with a known answer, and checking the output against the sentence it will support.
- **Retired function.** A function that still runs but has been replaced, such as `gather()` by `pivot_longer()`.
## Exercises {.unnumbered}
### Check Your Understanding {.exercises-check}
1. The opening chart ran without an error and was wrong in three ways. Name them, and name the column that would have exposed all three.
2. Why does a chart of growth in counts rank states by size rather than by change?
3. What is the difference between a check the model writes and a check you write from knowledge of the source?
4. Why keep the coverage summary in the finished document rather than deleting it once the chart is fixed?
### Apply It {.exercises-apply}
1. Ask a model for code that computes the change in `jail_rate` by state between 1990 and 2015 from the same file. Read the code before running it and list every claim it makes. Then run the coverage check from this chapter on `jail_reported`. Is jail coverage steadier than prison coverage? Which year has no jail data at all?
2. Ask a model to "explain each line" of the final chart code in this chapter. Mark any explanation that is wrong or incomplete.
3. Take a chunk from Chapter 11 of this book, introduce three errors (a misspelled function, a missing parenthesis, a wrong column name), and ask a model to find them. Record which it found and which it missed.
4. Ask a model to convert the final chart to a dot plot with the 1990 and 2013 rates as two points per state. Check that the states and values match the bar chart before accepting it.
### Think Deeper {.exercises-deeper}
1. A colleague says that since the model wrote the code, the model is responsible for the error. Write the reply you would give, in three sentences.
2. The coverage check in this chapter took two summaries and found the problem. Design the check you would have run if the dataset had no `prison_reported` column. What would you have had to know, and where would you have found it?
3. Some argue that tools which write code make learning R unnecessary. Others argue the reverse. Using the opening story, make the strongest case for each in one paragraph, then say which you find more persuasive and why.